AI Capability Maps: Documenting What Each Tool in Your Stack Does
Capability maps prevent duplicate subscriptions and shadow tools. Learn the fields to capture for every AI service.
Insights, guides, and latest trends from the world of AI tools
Capability maps prevent duplicate subscriptions and shadow tools. Learn the fields to capture for every AI service.
Context injection loads files, APIs, and memories into the prompt. Understand injection points and data-leak risks.
Batch endpoints process large job queues at lower cost. Learn when to choose batch mode and how SLAs differ from realtime.
Token buckets and request quotas throttle AI usage. Decode RPM, TPM, and concurrency limits on pricing pages.
Injection attacks hijack system instructions via user content. Learn defense layers vendors claim and how to validate them.
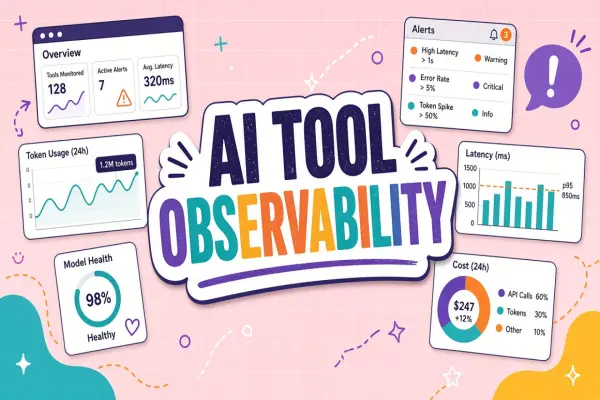
Observability tracks prompts, latencies, costs, and errors across AI pipelines. Learn the signals ops teams need from vendors.
Summarization, chunking, and compression reduce token load. Learn techniques vendors use to stretch context economically.
Fallbacks keep workflows alive when APIs error or quotas exhaust. Learn primary-secondary model patterns and user messaging.
Latency budgets cap end-to-end wait time for AI steps. Learn how to allocate milliseconds across retrieve, generate, and verify.
Didn't find tool you were looking for?