What Is Semantic Caching for AI? Cutting Repeat Inference Costs
Semantic caches store embeddings of prior queries to skip redundant LLM calls. Understand the savings mechanism and privacy implications.
Insights, guides, and latest trends from the world of AI tools
Semantic caches store embeddings of prior queries to skip redundant LLM calls. Understand the savings mechanism and privacy implications.
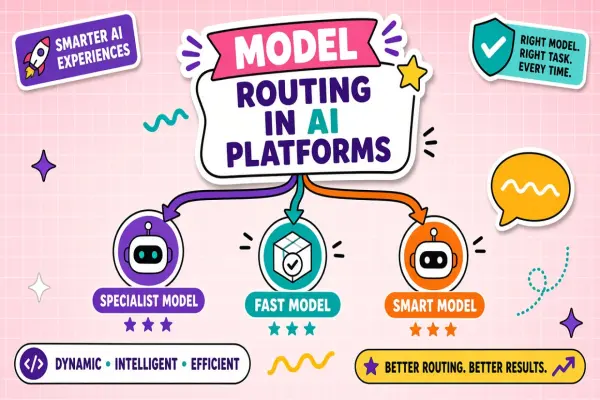
Model routers send each prompt to the cheapest or best-fit model automatically. Learn how routing policies work behind unified AI dashboards.
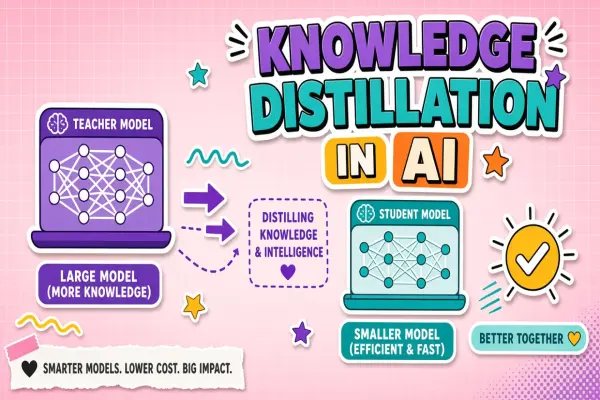
Distillation trains smaller models to mimic larger ones. Learn why vendors ship lite tiers and what capability you may lose.
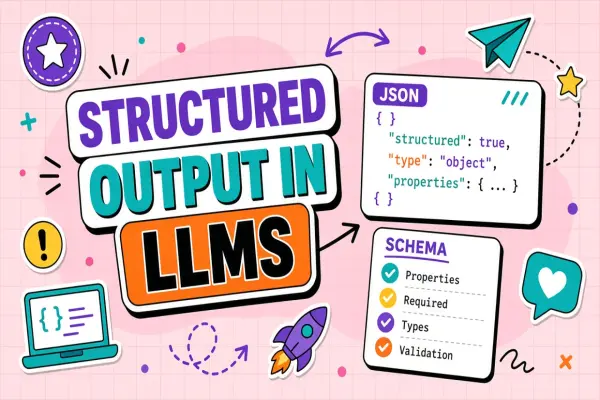
Structured output forces models to return JSON or schema-valid data. Learn when it works, when it fails, and how tools implement it.
Function calling lets LLMs trigger external APIs and actions. Learn how vendors implement it, what breaks in production, and how to evaluate tool-use claims.
Speculative decoding speeds up inference by drafting and verifying tokens in parallel. Understand the technique behind faster chat and coding assistants.
Schools face FERPA COPPA and academic integrity concerns with AI. Learn institutional policy patterns classroom use tiers and student data rules.
Newsrooms adopt AI for research and drafting under strict accuracy standards. Learn disclosure norms fact-checking workflows and source protection.
Nonprofits handle donor and beneficiary data on tight budgets. Learn low-cost adoption patterns grant compliance and ethical use of AI for mission work.
Didn't find tool you were looking for?