What Is Retrieval Reranking? Improving RAG Answer Quality
Rerankers reorder retrieved chunks before the LLM answers. Learn where reranking fits and how to spot weak RAG implementations.
Insights, guides, and latest trends from the world of AI tools
Rerankers reorder retrieved chunks before the LLM answers. Learn where reranking fits and how to spot weak RAG implementations.
Memory features persist facts across sessions. Learn storage types, consent models, and deletion rights before enabling memory.
Fusion models ingest multiple input types in one pass. Learn architecture basics and evaluation questions for multimodal tools.
Some tools show confidence or citation scores. Learn what these metrics actually measure and why they are not proof of truth.
Newer agents advertise deeper reasoning passes. Understand test-time compute, reflection loops, and when extra thinking helps.
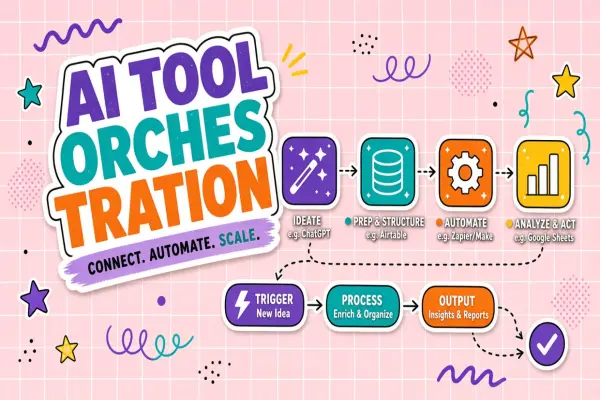
Orchestration coordinates multiple AI services into one workflow. Learn patterns, control planes, and where human checkpoints belong.
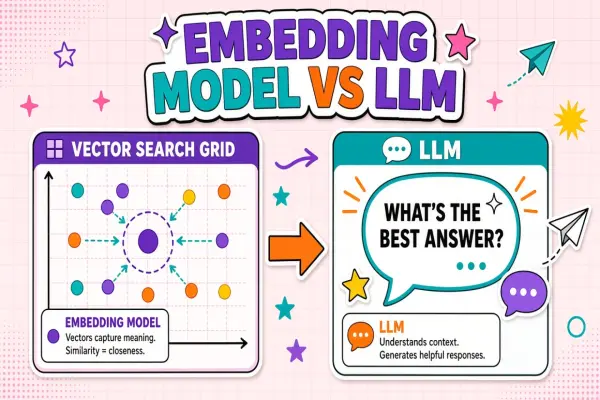
Embeddings power search and RAG; LLMs generate text. Clarify when you need each and how directories categorize both.
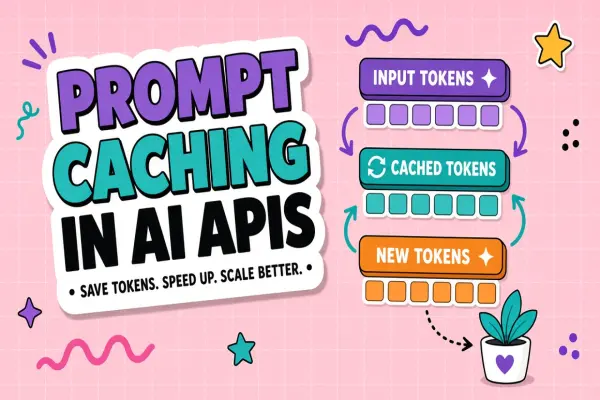
Prompt caching reuses unchanged prefix tokens to cut input costs. Learn eligibility rules, billing impact, and workflow design tips.
Million-token context sounds unlimited, but attention quality, cost, and latency change. Understand what long context actually delivers.
Didn't find tool you were looking for?