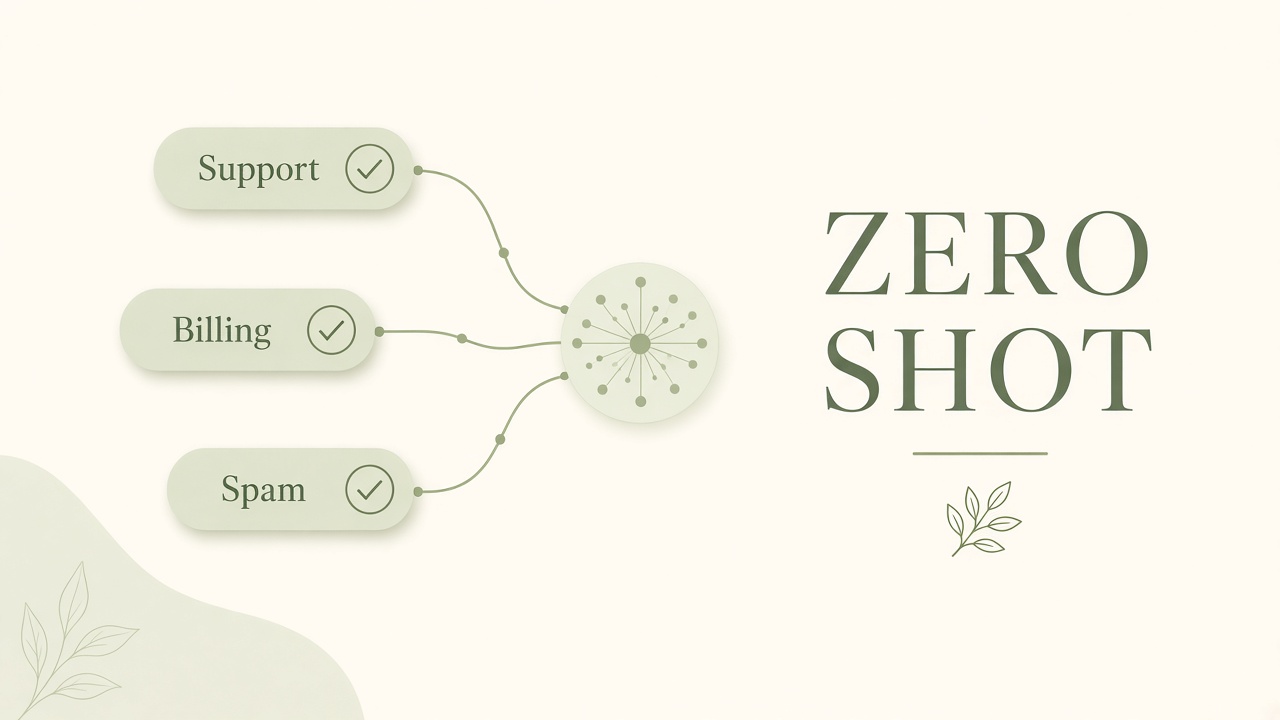
A support team wants to route incoming tickets into categories that change every quarter. Training a new supervised model for each taxonomy revision is slow and expensive. Zero shot classification ai offers a different path: describe each category in plain language, pass the ticket text to a language model or NLI-based classifier, and pick the label with the highest compatibility score. No labeled examples required for the new categories. Products in the AI chatbot space use zero-shot routing to triage intents, while AI productivity tools apply the same pattern to sort emails, notes, and tasks by topic without retraining pipelines.
Zero-Shot vs Supervised Classification
Supervised classifiers learn from thousands of labeled examples per class; zero-shot classifiers infer class membership from natural language descriptions of labels alone. Traditional text classifiers map input features to fixed numeric class IDs trained on historical data. Zero-shot systems treat classification as a language understanding problem: "Does this text entail the hypothesis that this item is a billing complaint?" Each candidate label becomes a hypothesis the model scores.
Supervised models excel when categories are stable, labels are abundant, and latency budgets are tight on commodity hardware. Zero-shot shines when taxonomy changes frequently, cold-start labeling is impossible, or you need ten provisional categories before investing in annotation. The tradeoff is consistency: supervised models optimize for your exact distribution; zero-shot models generalize from pretraining and may drift when label wording is ambiguous.
| Dimension | Supervised | Zero-shot |
|---|---|---|
| Training data | Hundreds to thousands per class | Label descriptions only |
| New category cost | Collect labels, retrain | Add or edit label text |
| Inference cost | Single forward pass | One score per label (or batched) |
| Edge cases | Reflects training distribution | Sensitive to label phrasing |
How Label Scoring Works
Zero-shot classifiers score each label by measuring semantic fit between the input text and a hypothesis formed from the label, typically via natural language inference or generative log-probability. NLI-based approaches pair the input as premise with "This text is about {label}" as hypothesis and read entailment probability. Generative approaches ask the model to rank labels by conditional likelihood. Embedding approaches compare the input vector to precomputed label description vectors using cosine similarity.
NLI vs generative scoring
Cross-encoder NLI models (BERT-family fine-tuned on MultiNLI) run one forward pass per label but capture interaction between premise and hypothesis tightly. Generative LLMs can classify with a single prompt listing all labels and requesting JSON output, reducing passes but increasing token cost and format fragility. For high-volume routing with twenty or more labels, batch NLI scoring or embedding similarity often wins on latency; for nuanced categories with long definitions, a capable LLM with structured output may score better.
| Scoring method | Strength | Weakness |
|---|---|---|
| NLI entailment | Strong pairwise fit signal | Linear cost in label count |
| Embedding similarity | Fast at scale | Weaker on subtle distinctions |
| LLM single prompt | Flexible label definitions | Higher token cost, parsing risk |
Writing Non-Overlapping Labels
Zero-shot accuracy collapses when label descriptions overlap semantically; each label needs a distinct, mutually exclusive definition with positive and negative cues. Labels like "Account issue" and "Login problem" confuse models because both entail similar text. Rewrite labels as "User cannot sign in (password, MFA, SSO)" versus "Billing, subscription, or payment dispute" with explicit exclusion clauses. Include one "none of the above" or "other" bucket so the model can abstain instead of forcing a weak best match.
Label order bias affects generative classifiers: models may favor labels listed first. Shuffle label order in evaluation and use calibrated scores rather than raw logits when comparing across runs. Document label definitions in a taxonomy registry so product and ops teams edit wording deliberately, not ad hoc in prompts.
Calibration and Confidence Thresholds
Raw zero-shot scores are not calibrated probabilities; apply temperature scaling, Platt scaling, or human-labeled validation sets to set routing thresholds. A ticket scored 0.62 for "Shipping delay" and 0.58 for "Product defect" should not auto-route on a thin margin. Production systems hold ambiguous cases for human review, route only when top score exceeds a tuned threshold and margin to second place exceeds a delta, and log score distributions weekly to detect drift.
Threshold tuning workflow
- Sample five hundred historical items with human gold labels.
- Run zero-shot scorer with current label definitions.
- Plot precision-recall per class at varying thresholds.
- Set auto-route threshold where precision meets SLA (often 0.85+).
- Send below-threshold items to review queue with top three labels displayed.
Human Review in Zero-Shot Pipelines
Zero-shot classification should feed human review loops, not replace them on high-stakes routing until calibrated performance matches supervised baselines on your data. Reviewers confirm or correct predictions; corrections become labeled data for eventual supervised fine-tuning or few-shot exemplars in prompts. Displaying the top three labels with scores helps reviewers decide faster than reading raw ticket text alone. Track disagreement rate between model and reviewers; spikes often indicate taxonomy drift or ambiguous new product lines.
For regulated content (medical triage, legal intake), treat zero-shot output as a draft suggestion only. Audit logs should store label definitions version, model version, scores, and reviewer overrides for compliance. Never silently auto-close tickets on zero-shot alone during the first month of a new taxonomy.
Production Architecture Patterns
Mature zero-shot stacks combine a fast embedding pre-filter, NLI rerank on top five labels, and a fallback LLM for ties or low-confidence cases. Pre-filtering with embeddings reduces NLI calls from forty labels to five. Cache label embedding vectors when definitions are static. Async workers score backlog tickets; real-time chat may use smaller distilled NLI models. Version label YAML in git and deploy with CI tests that assert golden tickets still route correctly.
| Stage | Purpose | Typical latency |
|---|---|---|
| Embedding shortlist | Narrow to top k labels | 10 to 30 ms |
| NLI rerank | Precise entailment scores | 50 to 200 ms |
| Threshold gate | Auto-route or queue review | Under 5 ms |
Multilingual Zero-Shot in Global Teams
Global support queues mix languages; zero-shot classifiers must either use multilingual NLI models or normalize language before scoring. A ticket written in Brazilian Portuguese scored against English-only label hypotheses underperforms even when the topic is obvious to a human bilingual reviewer. Practical stacks detect language first, select label translations from a taxonomy registry, and run scoring in the ticket language. For low-resource locales, fall back to English labels only after benchmarking shows acceptable recall. Document which languages are production-supported versus experimental so CS managers set correct expectations.
Mixed-language tickets (product names in English inside Hindi body text) appear frequently in SaaS support. Embedding shortlists trained on multilingual corpora often survive this better than monolingual NLI. Run monthly evals per locale; a global average F1 can hide catastrophic failure in a revenue-critical market.
Cost Modeling for High-Volume Routing
Finance teams should model zero-shot cost as (tickets per month) times (labels scored) times (price per inference), not as a flat API subscription. At fifty thousand tickets daily with forty labels via cross-encoder NLI, inference dominates the bill unless shortlisting cuts labels to five. Distilled student models (smaller BERT variants) reduce cost with modest F1 loss. Batch scoring during off-peak hours works for async queues but not live chat. Compare against outsourced human triage: even expensive zero-shot may beat BPO cost per ticket when precision exceeds eighty percent on auto-route paths.
Vendor evaluation checklist
- Can you bring custom label definitions without retraining?
- Does the API return per-label scores for audit, not only argmax?
- Is there a sandbox with your taxonomy for two-week POC?
- How are model upgrades announced and can you pin versions?
- What PII handling applies to ticket text sent to cloud inference?
Monitoring Drift and Taxonomy Governance
Taxonomy drift is the silent killer of zero-shot pipelines: marketing renames features, legal splits categories, and label descriptions rot while scores still look numerically confident. Assign a taxonomy owner who approves label edits through pull requests with required golden-set regression. Dashboard score distributions per label; sudden spikes in "Other" or flat entropy across top two labels signal definition overlap. When base models upgrade, rerun full eval before promoting to production. Tie taxonomy version strings to routing logs so incident postmortems trace which wording was live when a misroute occurred.
When Zero-Shot Is the Wrong Tool
Skip zero-shot when you need deterministic rules on structured fields, sub-millisecond latency at huge scale, or legally binding classification without human sign-off. Regex and keyword rules beat zero-shot on SKU codes and error IDs. After you accumulate ten thousand verified labels, a small supervised model often beats zero-shot on accuracy and cost. Zero-shot remains valuable for taxonomy prototyping and long-tail categories that rarely appear.
Frequently Asked Questions
Does zero-shot classification work across languages?
Multilingual embedding and NLI models handle many languages, but label descriptions must match the input language or use a consistent pivot language with verified performance. Mixed-language tickets (English product names in Spanish support text) need evaluation on real samples. Translate labels professionally rather than machine-translating taxonomy without review.
How much does zero-shot classification cost at scale?
Cost scales with label count for NLI approaches and with tokens for LLM prompts; embedding shortlists reduce both. One million tickets with thirty labels via cross-encoder NLI differs sharply from one LLM call per ticket. Benchmark on your hardware before committing; distilled models trade small accuracy loss for large savings.
What causes zero-shot classification drift?
Drift appears when product vocabulary changes, label wording edits shift entailment scores, or the base model is upgraded without regression tests. Run weekly golden-set evals. When marketing launches new feature names, update label descriptions and revalidate thresholds before auto-routing resumes.
Can few-shot examples improve zero-shot?
Adding two or three examples per label in the prompt bridges zero-shot and few-shot, often lifting accuracy without full supervised training. Examples must be diverse and refreshed when categories evolve. Store exemplars in version control alongside label definitions.
Is zero-shot the same as sentiment analysis?
Sentiment is a specialized classification task with fixed polarity labels; zero-shot is the general pattern of scoring arbitrary natural language categories. You can run sentiment zero-shot with labels "positive," "negative," and "neutral," but domain-specific sentiment often still benefits from labeled fine-tuning.
Integrating Zero-Shot with Downstream Automation
Classification output triggers workflows: assign CRM owner, select macro reply, or enqueue SLA timer; zero-shot scores should include confidence metadata for each automation branch. Low-confidence routes should never trigger irreversible actions (account suspension, refund approval). Use composable pipelines: zero-shot suggests label, rules engine validates against structured fields (product SKU, country code), then automation fires. This hybrid beats pure rules on messy free text while keeping deterministic guardrails on structured data. Log the full decision chain for compliance audits.
Conclusion
Zero-shot classification assigns categories using label descriptions instead of task-specific training data. Score fit with NLI, embeddings, or LLM prompts; write mutually exclusive labels; calibrate thresholds; and keep humans in the loop until metrics prove safe auto-routing. The pattern fits fast-changing taxonomies in chatbots and productivity workflows, but plan a path to supervised or few-shot refinement once volume and stakes grow.