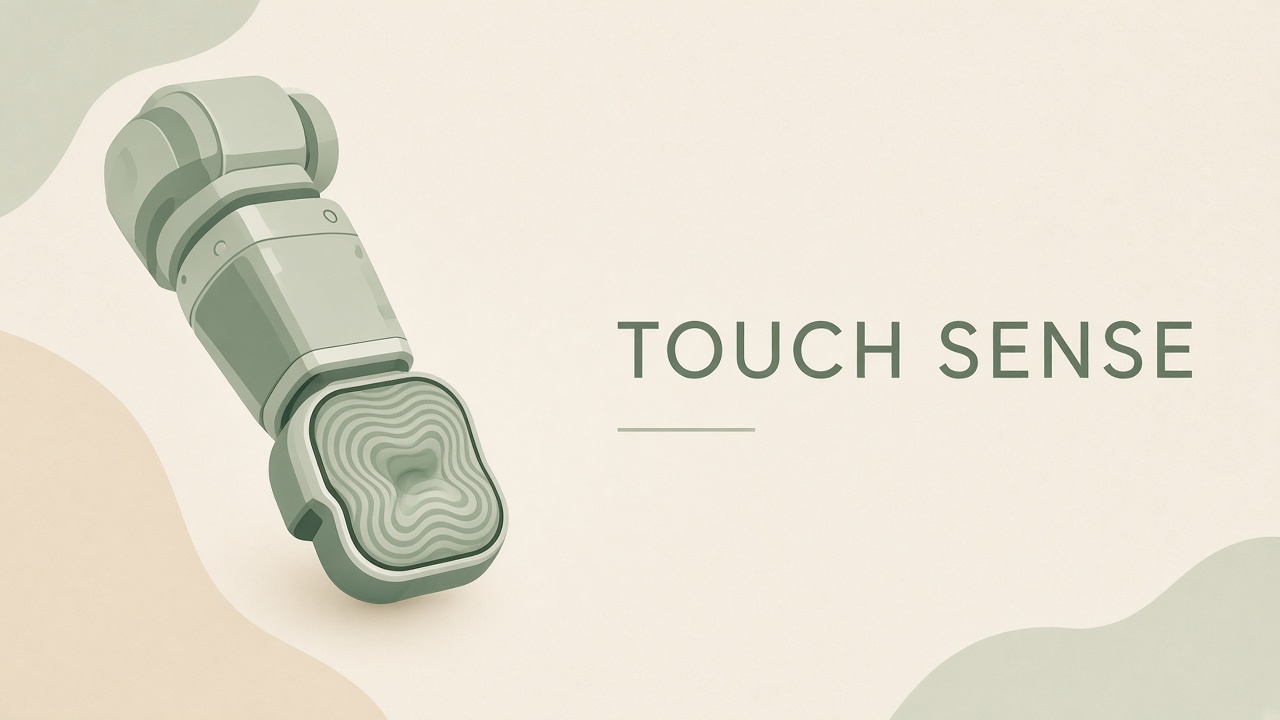
A robot arm can see a USB connector and a port, yet still miss the insertion by millimeters because cameras lose detail once the gripper occludes the view. Contact forces, slip, texture, and local geometry matter at the moment the fingertips meet the object. That gap is where tactile sensing robot manipulation AI enters: machine learning policies that combine vision with touch streams from GelSight Mini, DIGIT, or similar optical tactile sensors to close the loop on precision grasping, peg insertion, and force-aware handling of fragile items.
Warehouse pick stations, electronics assembly lines, and research labs evaluating AI chatbot assistants for operator documentation still depend on vision-only stacks that fail under glare, clutter, or partial occlusion. Tactile-augmented imitation learning is moving from niche papers into reproducible benchmarks like ManiFeel and UniVTAC. For broader context on how research teams publish technical explainers, browse the EliteAI.tools blog index.
What Tactile Sensing Robot Manipulation AI Means in Plain Language
Tactile sensing robot manipulation AI is the use of machine learning to interpret contact measurements from robot-mounted touch sensors and fuse those signals with vision and proprioception to choose grasp forces, motions, and recovery actions during physical interaction. A tactile sensor converts mechanical contact into data: optical sensors like GelSight Mini capture gel deformation as images; DIGIT and Digit360 sensors do the same at fingertip scale; force-torque cells at the wrist report aggregate loads but not local contact geometry.
Vision-only policies treat touch as an afterthought or ignore it entirely. Visuotactile policies encode tactile images or derived force fields alongside RGB frames, then train with behavioral cloning, diffusion policies, or transformer action chunking (ACT). The AI component learns when to increase grip force, when to re-search after slip, and when visual similarity between objects (a table tennis ball versus a golf ball) requires contact discrimination that cameras alone cannot resolve.
| Sensor family | Output type | Strength | Typical limitation |
|---|---|---|---|
| Optical gel (GelSight Mini) | High-res contact image | Texture, geometry, shear field | Bulk, calibration for absolute force |
| Fingertip optical (DIGIT, Digit360) | Compact tactile image | Dexterous hand integration | Durability on sharp edges |
| Wrist F/T sensor | 6-axis wrench | Simple integration | No spatial contact map |
| Taxel arrays (Xense, DMA) | Pressure grid or events | Thin form factors | Lower resolution than gel optics |
When touch beats vision alone
Tactile sensing helps most when tasks require contact-state discrimination, precise force control, or recovery after disturbance while the manipulated object is visually occluded. ManiFeel benchmark results show visuotactile policies outperforming vision-only baselines on USB insertion, bulb screwing, gear assembly, and object search under dim lighting. In ball sorting, a visuotactile policy detects when a human removes an object mid-rollout and re-initiates search; a vision-only policy often fails to respond.
How the Underlying AI Pipeline Works
A typical visuotactile pipeline collects human demonstrations with synchronized RGB and tactile streams, encodes each modality with separate neural networks, fuses features, and trains an action policy that outputs end-effector poses, gripper width, or explicit force targets. Representation choices matter: raw tactile RGB (TacRGB), learned force fields (TacFF), and temporal difference features each emphasize different contact cues. GelFusion (2025) uses dual-channel tactile encoders for static geometry and dynamic interaction, fused with vision through a vision-led cross-attention block.
Policy architectures in current research
Diffusion policies model multimodal action distributions and dominate recent contact-rich manipulation papers. Reactive Diffusion Policy (RDP), published at RSS 2025, splits planning into a slow visual diffusion head and a fast tactile reactive head, reporting greater than 35 percent improvement over imitation learning baselines on wiping, insertion, and fragile pick-and-place with GelSight Mini and MCTac sensors. Force-Aware Robotic Manipulation (FARM) extends the Universal Manipulation Interface gripper with GelSight Mini and predicts grip force directly in the action space, alternating position and closed-loop force control at deployment.
Action Chunking with Transformers (ACT) appears in UniVTAC, a 2026 simulation benchmark built on NVIDIA Isaac Lab and TacEx, where researchers compare ACT, ViTAL tactile-vision encoders, and ablation variants across HDMI insertion, peg-in-hole, and grasp-classify tasks. Tube Diffusion Policy targets lower latency for dexterous Allegro-hand manipulation with Digit360 fingertip sensors, addressing the denoising delay that limits purely diffusion-based reactive control.
| Framework | Core idea | Reported strength |
|---|---|---|
| GelFusion | Dual-channel tactile + vision cross-attention | Wiping, peg insertion, fragile grasp |
| Reactive Diffusion Policy | Slow-fast visual-tactile diffusion | Disturbance rejection, bimanual tasks |
| FARM | Force in action space + FEATS estimation | High-force, low-force, dynamic adaptation |
| ManiFeel | Benchmark + TacRGB/TacFF encoders | Systematic modality comparison |
| UniVTAC | Sim data generation + ACT/ViTAL training | Reproducible tactile sim tasks |
Typical workflow steps
- Mount optical tactile sensors on gripper fingers or dexterous hand tips; calibrate gel lighting and baseline images.
- Collect 50 to 500 teleoperated demonstrations per task with synchronized wrist/global cameras and tactile frames.
- Choose tactile representation (TacRGB images, TacFF fields, or temporal difference maps).
- Train a visuotactile policy (diffusion, ACT, or CNN-MLP baseline) with held-out validation trajectories.
- Sim-to-real transfer optional: pretrain in ManiFeel or UniVTAC, fine-tune on real hardware.
- Evaluate success rate, force profiles, and recovery behavior under lighting changes and human disturbances.
- Document sensor model, policy checkpoint, and control frequency for reproducibility.
Real Deployments and Published Evidence
Visuotactile manipulation AI has progressed from isolated lab demos to open-source teleoperation stacks, simulation benchmarks, and cross-sensor evaluation suites published between 2024 and 2026. The Reactive Diffusion Policy team releases TactAR teleoperation code and reports real-robot experiments across GelSight Mini, MCTac, and joint torque sensing with consistent performance. FARM open-sources hardware designs for an actuated UMI gripper matched to handheld demonstration geometry, reducing retargeting error at deployment.
ManiFeel, from Purdue MARS Lab, simulates GelSight sensors in IsaacGym/TacSL and publishes datasets on Hugging Face for USB insertion, ball sorting, and related tasks. Real-world rollouts transfer sim-trained TacRGB and TacFF policies to physical robots with documented success and failure modes. TLabel-Bench (2026 direction) addresses a long-standing gap: cross-sensor annotations for GelSight Mini, DIGIT, DMA, and Xense on identical objects, enabling fair comparison of tactile encoders rather than sensor-specific datasets that cannot transfer.
GelFusion authors evaluate three contact-rich tasks with self-built GelSight sensors and report improved success rates over vision-only and naive fusion baselines, attributing gains to dual-channel tactile features and vision-dominated fusion that prevents tactile noise from drowning visual cues. Industry-adjacent deployments remain mostly in research consortia and advanced manufacturing pilots; commercial integrators increasingly specify tactile-ready grippers but rarely ship pretrained visuotactile policies out of the box.
Simulation and data scale
UniVTAC generates expert demonstrations with simulated GelSight Mini contact physics for tasks like HDMI insertion, pull-out-key, and grasp-classify. The platform supports ACT training with and without tactile inputs so teams can quantify modality contribution before buying hardware. Simulation fidelity for gel optics still lags real gel wear, temperature drift, and marker dot degradation, so sim-to-real gaps persist unless fine-tuned on a small real dataset.
Limits, Risks, and Ethical Guardrails
Tactile sensing robot manipulation AI fails when sensors wear out, calibration drifts, policies overfit to demonstration lighting, or force limits are mis-specified for human proximity. Optical gel pads scratch and discolor; repeated high-force contacts change tactile appearance and invalidate pretrained encoders. Absolute force estimation from gel images still requires calibration routines that many learning papers skip, reporting success rates without publishing peak contact forces near human-safe limits.
- Latency: High-resolution tactile frames at 25 to 60 FPS compete with diffusion inference; slow-fast architectures exist partly to hide this bottleneck.
- Sensor lock-in: Policies trained on GelSight Mini features may degrade on DIGIT without domain adaptation; TLabel-Bench aims to measure this drop quantitatively.
- Sim gap: TacSL and TacEx simulate contact well but not long-term gel material changes.
- Safety: Learned force commands can exceed safe limits if demonstrations included aggressive grasps; hardware force caps remain mandatory.
- Label scarcity: Tactile data is harder to annotate than RGB; self-supervised encoders help but obscure failure diagnosis.
Ethical guardrails include keeping humans outside the robot workspace during autonomous rollouts until force and speed limits are validated, documenting demographic and object diversity in demonstration datasets, and avoiding overstated generalization from benchmark tasks (USB insertion) to unstructured homes or hospitals. Tactile AI should augment operator skill, not replace safety engineering or mechanical safeguards.
Who Should Use This and Who Should Wait
Robotics labs working on contact-rich assembly, dexterous manipulation, or slip recovery should adopt visuotactile learning now, starting with open benchmarks and one proven sensor family before scaling hardware diversity. Teams with only pick-and-place from open bins under good lighting may not justify tactile hardware cost until failure analysis shows occlusion or force errors dominate downtime.
| Audience | Recommendation | Caveat |
|---|---|---|
| University robotics lab | Start with ManiFeel or UniVTAC, one GelSight or DIGIT setup | Budget for gel replacement and teleop time |
| Manufacturing R&D | Pilot RDP or FARM on one insertion or force-critical station | Validate cycle time and maintenance SOPs |
| Startup building embodied AI | Invest in tactile data collection early | Cross-sensor generalization remains open research |
| Warehouse operator | Wait for vendor-validated tactile SKUs | Off-the-shelf tactile policies are rare today |
Groups without GPU inference hardware can still collect tactile datasets on edge PCs and train offline, but reactive policies like RDP assume low-latency loops. Hybrid approaches that use tactile sensing only during contact phases (free-space motion vision-only) reduce compute and sensor wear while preserving most gains on insertion and grasp-adjust tasks.
Integration checklist before production pilots
Before scaling beyond bench tests, document sensor serial numbers, gel batch IDs, camera exposure settings, and policy checkpoint hashes in every run log. Calibrate force-torque references against a known load cell quarterly. Define rollback criteria: if slip recovery success drops below an agreed threshold over a rolling seven-day window, revert to the prior checkpoint and inspect gel wear before retraining. Pair tactile policies with independent workspace monitors (light curtains, pressure mats, or rated stop chains) so a corrupted tactile frame cannot drive motion through a safety envelope alone.
Frequently Asked Questions
How much better is tactile sensing robot manipulation AI than vision only?
Reported gains depend on the task: ManiFeel and GelFusion show large improvements on insertion, screwing, and visually ambiguous sorting, while simple reach-and-grasp under good lighting may show modest differences. Treat published percentages as benchmark-specific; run ablations on your station before committing to sensor hardware.
Should I use GelSight Mini or DIGIT?
GelSight Mini suits parallel-jaw grippers and high-resolution contact patches; DIGIT and Digit360 target dexterous fingertips and multi-contact hands. Reactive Diffusion Policy reports similar scores across GelSight Mini and MCTac on shared tasks, suggesting encoder quality and demonstration coverage matter as much as brand choice.
What is the difference between TacRGB and TacFF representations?
TacRGB feeds raw or normalized tactile images into the policy; TacFF encodes contact as learned force-field features that ManiFeel often finds more robust than tactile RGB alone. Choice affects sim-to-real transfer and training stability; try both on a small dataset before scaling collection.
Is visuotactile manipulation AI regulated?
Industrial robot safety standards (ISO 10218, ISO/TS 15066 for collaborative robots) govern workspace design and force limits, not specific AI architectures. Learned tactile policies do not replace risk assessment, guarding, or emergency stops required for commercial deployment.
How many demonstrations do tactile policies need?
Published contact-rich tasks often use tens to hundreds of teleoperated trajectories per skill; sim pretraining in UniVTAC or ManiFeel can reduce real-world collection but rarely eliminates it entirely. Data needs rise with object diversity, dual-arm coordination, and explicit force targets.
Can I train entirely in simulation?
Simulation helps for algorithm comparison and initial policy weights, but gel sensor appearance and contact physics on real hardware still require fine-tuning demonstrations. UniVTAC and ManiFeel explicitly support sim-to-real experiments with documented gaps.
How often do optical tactile sensors need maintenance?
Gel surfaces accumulate wear and contamination; labs report periodic cleaning and gel replacement depending on contact frequency and object sharpness. Policies trained on fresh gel may degrade silently as tactile images drift; monitor success rate and tactile baseline statistics in production.
Conclusion
Tactile sensing robot manipulation AI closes the contact-information gap that limits vision-only policies on insertion, force control, slip recovery, and visually ambiguous objects. GelSight Mini, DIGIT, and related optical sensors feed high-dimensional touch streams that fusion frameworks like GelFusion, Reactive Diffusion Policy, and FARM combine with vision for learned manipulation. Benchmarks including ManiFeel, UniVTAC, and emerging cross-sensor suites like TLabel-Bench make comparisons more reproducible. Success still depends on demonstration quality, sensor maintenance, latency-aware control, and hardware safety limits that learning cannot remove. Teams should benchmark tactile gain on their own tasks, document sensor and policy versions, and treat touch as core sensing rather than an optional debug channel.