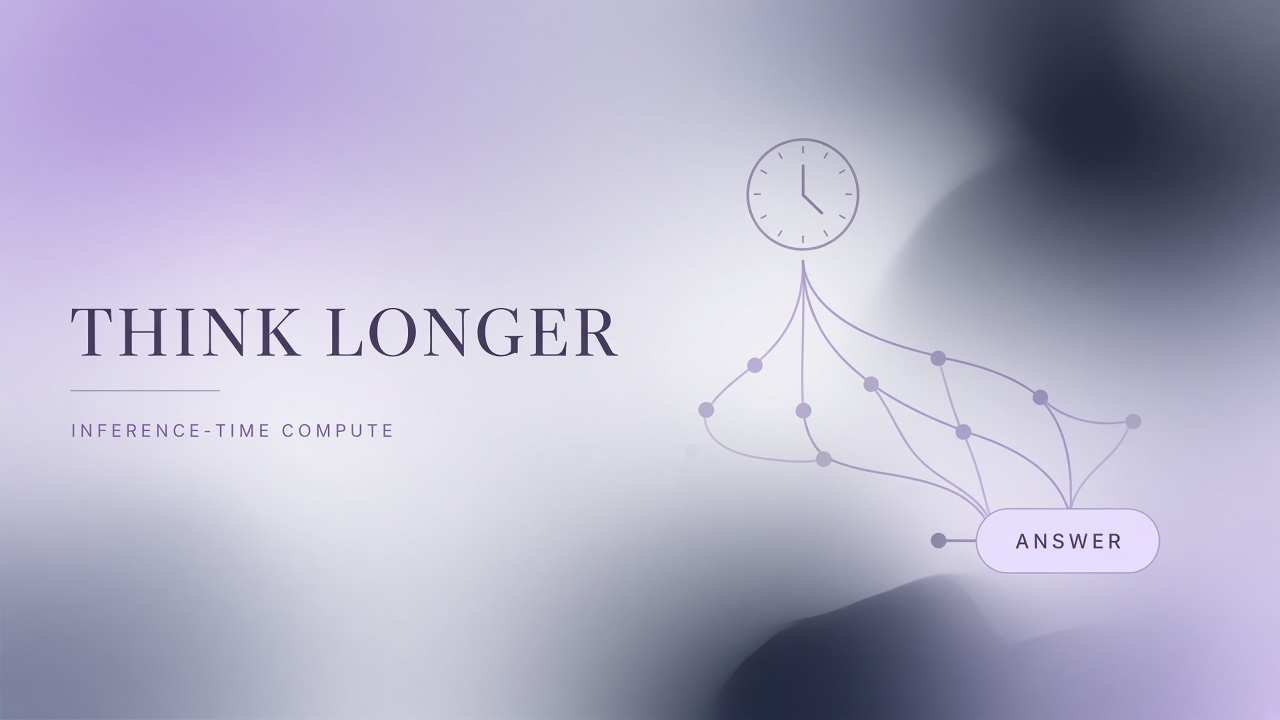
Two users ask the same math word problem. One model answers in two seconds with a single pass; another thinks for fifteen seconds, drafts multiple reasoning paths, and returns the answer that survived self-checking. Inference time compute ai describes spending extra FLOPs, tokens, or sequential model calls during inference to improve quality on hard tasks. Training-time compute builds the model once; inference-time compute buys accuracy per question. Advanced AI chatbot products expose "extended thinking" modes; AI writing assistants use multi-draft generation before presenting a polished paragraph.
Training Compute vs Inference Compute
Training compute updates billions of parameters over many GPU-hours on large corpora; inference compute runs the fixed model forward (and sometimes backward-free search) on each user query. Scaling laws historically emphasized bigger pretraining runs. Recent research and products shift some budget to test-time scaling: letting models reason longer, sample multiple completions, or run tool loops before finalizing output. Users pay inference compute as latency and per-token API charges, not as a one-time cluster bill.
| Phase | When it runs | Who pays |
|---|---|---|
| Pretraining | Once per base model | Provider capex |
| Fine-tuning | Per task adapter | Customer or provider |
| Inference-time compute | Every hard query | Per-request opex |
Chain-of-Thought, Voting, and Search
Common inference-time techniques include chain-of-thought (CoT) prompting, self-consistency voting across multiple samples, tree-of-thought search, and agentic tool loops. CoT asks the model to emit intermediate reasoning steps before the final answer, increasing output tokens but reducing arithmetic and logic errors. Self-consistency generates N independent reasoning traces and majority-votes the conclusion. Search methods explore branches, score partial solutions, and prune weak paths. Each extra sample multiplies token cost and wall-clock time roughly linearly unless batched on specialized hardware.
Test-time scaling
Test-time scaling allocates more compute when problem difficulty estimates are high. A router sends simple FAQs to a fast single-pass model and routes exam-style questions to a reasoning model with extended token budget. Difficulty classifiers can be small models or heuristics (length, domain, user tier). Without routing, every user subsidizes the hardest queries.
| Technique | Compute multiplier | Typical gain |
|---|---|---|
| CoT (single trace) | 1.5x to 3x tokens | Math, logic, multi-step |
| Self-consistency (N=5) | ~5x generation | Robustness on stochastic models |
| Agent tool loop | Variable rounds | Fresh data, code execution |
When Extra Inference Compute Helps
Extra inference compute pays off on tasks with verifiable reasoning steps, high error cost, and low query volume relative to value; it rarely helps simple retrieval or templated replies. Legal analysis, complex coding, scientific derivation, and competition math benefit. Summarizing a short email does not. Measure uplift on a golden set: if five-sample voting adds two points accuracy but triples latency, only enable it for paid tiers or explicit "deep analysis" buttons.
Models trained with reinforcement learning on reasoning (RLVR) may use internal extended thinking tokens before visible answers. Providers bill hidden reasoning tokens separately on some APIs. Budget accordingly when migrating from classic chat completions to reasoning-native endpoints.
UX: Thinking Indicators and Latency
Users tolerate longer waits when the interface shows progress: thinking indicators, partial reasoning summaries, and cancel buttons. Sudden fifteen-second silence feels broken; streamed "working through step 2 of 4" builds trust. Set expectations in the UI label ("Extended thinking may take up to 60 seconds"). Offer a fast mode default with opt-in depth. Mobile users abandon faster; cap max thinking time per platform. Log abandonment rate versus quality scores to tune defaults.
Latency budgeting
- Define p95 targets per product surface (chat vs batch report).
- Cap max samples and tool rounds per tier.
- Stream tokens so time-to-first-byte stays low even when total time grows.
- Timeout gracefully with partial answer plus "could not finish deep analysis."
- Cache reasoning traces only when inputs are deterministic and privacy allows.
Measuring Value of Inference-Time Compute
Measure value as accuracy or task success uplift divided by added latency and token cost, segmented by query type. Track pass rate on eval benchmarks, human thumbs-up, downstream conversion (merged PR, ticket resolved), and cost per successful outcome. A/B test thinking mode against baseline on live traffic with guardrails for safety regressions. Report metrics to finance as incremental COGS per successful task, not raw token totals alone.
| Metric | Question it answers | Action if bad |
|---|---|---|
| Success rate delta | Worth the extra compute? | Disable on low-uplift segments |
| p95 latency | UX acceptable? | Reduce N or cap tokens |
| Cost per success | Sustainable margin? | Tier-gate deep mode |
| Abandonment rate | Users wait? | Improve progress UI |
Product Patterns for Reasoning Modes
Ship reasoning as explicit modes (Standard vs Research), per-message upsell, or automatic routing behind the scenes. Explicit modes set user expectations and simplify billing. Automatic routing maximizes quality but complicates support when users do not know why one answer took longer. Document which mode was used in logs for debugging. Enterprise contracts may cap monthly reasoning tokens; enforce quotas in API gateways.
Hardware and Batching for Multi-Sample Inference
Self-consistency and parallel CoT samples benefit from GPU batching; sequential API calls multiply wall clock time linearly. When hosting open models, batch five samples in one forward pass where memory allows. API providers may offer parallel completion endpoints; verify rate limits before enabling deep mode for all users. KV-cache reuse across samples sharing a prefix (same system prompt) cuts cost on some inference servers. Profile before launch: theoretical 5x tokens does not always mean 5x wall time with good batching.
Combining Inference-Time Compute with Tools
Agent loops are inference-time compute: each tool call adds a model round trip plus external latency (search, SQL, code sandbox). Cap max iterations (often three to ten) and total wall time. Verifiers (run unit test, execute calculator) convert open-ended reasoning into checkable steps. Tool-heavy paths need different UX than silent CoT: show which tool ran and whether it succeeded. Billing must account for tool API costs plus model tokens across rounds.
| Pattern | Extra compute source | Best fit |
|---|---|---|
| Long CoT | Output tokens | Math, logic puzzles |
| Tool agent | Multiple model calls | Live data, code run |
| Verifier loop | Generate + check cycles | Structured outputs |
Enterprise Governance of Reasoning Modes
Security and legal teams increasingly ask whether hidden reasoning traces store PII or bypass content filters. Configure logging policies: some vendors allow opting out of training on reasoning tokens but still log for abuse monitoring. Air-gapped deployments may disable extended thinking entirely. Procurement should ask SLA for max latency on reasoning endpoints and whether quotas are soft or hard caps. Document which employee tiers may enable deep research on customer data.
Limits and Failure Modes
More inference compute does not fix bad retrieval, wrong tools, or fundamental knowledge gaps; it can amplify confident errors in long chains. Long CoT traces leak intermediate mistakes into final answers if voting pools are small. Tool loops may hallucinate API calls. Cap iteration count and require verifiers (unit tests, calculator, retrieval check) where possible. Safety policies must apply to hidden reasoning channels, not only final outputs.
Frequently Asked Questions
Is inference-time compute the same as using a bigger model?
Related but distinct: bigger models raise quality per pass; inference-time techniques add passes or search on a given model. Sometimes a smaller model plus voting matches a larger single-pass model at lower average cost on hard subsets only.
How do APIs bill extended thinking?
Providers may charge for reasoning tokens, output tokens, and tool calls separately. Read pricing pages for reasoning models; hidden token counts can exceed visible answers. Monitor usage dashboards after enabling deep modes.
When should I disable extra inference compute?
Disable for low-stakes, high-QPS paths, strict sub-second SLAs, and tasks with external verifiers that already catch errors cheaply. Re-enable for paid analyst workflows and batch offline jobs.
What is the link to "reasoning models"?
Reasoning models are trained to use long internal chains at inference by default; classical models need explicit CoT or voting wrappers. Both consume inference-time compute; integration and pricing differ by vendor.
Does inference-time compute work on edge devices?
Self-consistency and long CoT multiply local inference cost; edge deployments usually limit to single pass or distilled small models. Cloud offload for deep modes on mobile apps is common.
Competitive Landscape: Reasoning Products
Major model families now market native extended thinking (OpenAI o-series, Anthropic extended thinking, Google Deep Think-style modes) as differentiated SKUs with separate rate limits and pricing. Builders choose between wrapping classic models with self-consistency versus adopting reasoning endpoints with opaque internal token use. Abstraction layers should hide provider specifics but expose mode, latency, and cost to product analytics. Benchmark your golden set on both paths before standardizing architecture.
Caching and Memoization Strategies
Deterministic analytical questions (same spreadsheet uploaded daily) can memoize final answers keyed by input hash, skipping repeated inference-time compute. Do not cache personalized or time-sensitive outputs without TTL and privacy review. Partial cache of retrieval results helps agent loops without caching full reasoning traces that may contain sensitive intermediate steps. Invalidate cache when underlying tools or documents change version.
Offline Batch Jobs and Inference-Time Compute
Batch report generation and code review bots can afford ten-sample self-consistency where interactive chat cannot. Schedule heavy inference overnight when GPU queues are cheap. Separate job tiers from realtime API pools so long-running reasoning does not starve quick replies. Progress emails or webhook callbacks replace streaming UX for batch. Charge enterprise customers per report page when deep analysis is the product value, not per chat message.
Safety Implications of Longer Reasoning
Extended reasoning traces may explore harmful intermediate steps even when final answers are filtered; safety classifiers must run on hidden channels where providers expose them. Jailbreak attempts that succeed on single-pass models may fail or succeed differently under multi-sample voting. Red-team reasoning modes separately from standard chat. Log refusal rates by mode; deep thinking should not weaken policy compliance. Enterprise buyers ask whether reasoning tokens appear in support exports; clarify in DPA.
Future Trends in Test-Time Scaling
Research continues on learned stopping policies (when to halt reasoning), verifier-trained models, and hardware optimized for long decode sequences. Product teams should expect reasoning token budgets to rise on flagship models while mid-tier SKUs stay single-pass for cost-sensitive workloads. Monitor provider roadmaps quarterly; abstractions that hardcode one sampling strategy may need refactor as APIs evolve. Budget engineering time each quarter to retune routing thresholds as model capabilities shift. Product analytics should segment conversion and satisfaction scores by reasoning mode so leadership sees whether depth pays off for each customer segment.
Conclusion
Inference-time compute trades latency and tokens for better answers on hard problems through chain-of-thought, voting, search, and agent loops. Separate training from test-time scaling, route expensive paths deliberately, design UX for longer waits, and measure uplift per dollar and per second. Use it where error cost justifies the bill, not as a default on every chat message.